The Loop Is Closing: METR Says AI Is Now Building AI Twice as Fast
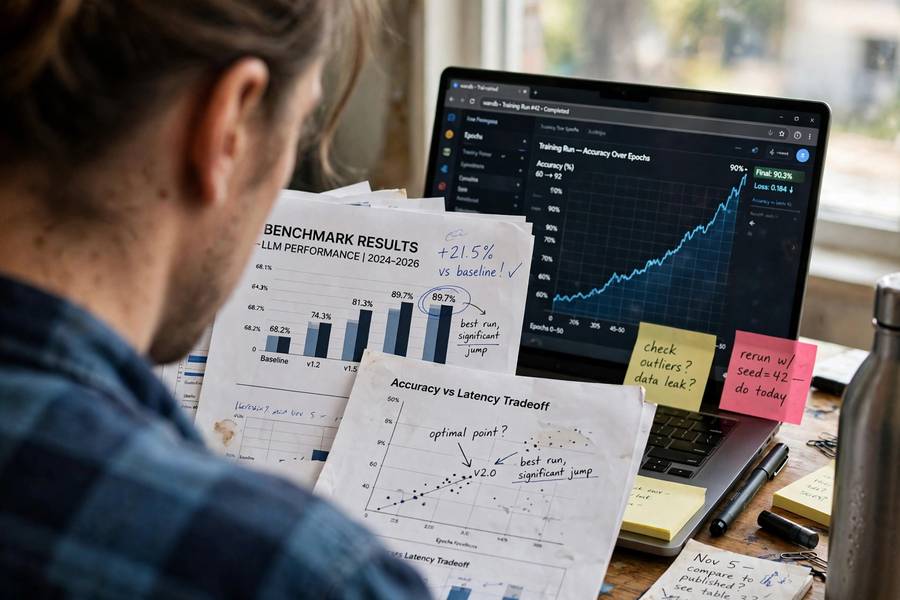
The most consequential AI report of the year is not about a model. It is about the factory that makes the models. On November 5, METR — the independent AI evaluation nonprofit — published an 11-week assessment conducted inside Anthropic, and its headline number should reframe every argument about how fast this technology is moving: Anthropic’s models have been improving about 1.9 times faster since October 2025 than they did before, and most of that speedup comes from AI doing the research itself.
Measured on AECI, Anthropic’s version of the Epoch Capabilities Index, benchmark scores rose about 15 points a year before October 2025 and about 29 points a year after it — a trend break METR dates to October 7, 2025. In plain terms, Anthropic made roughly two years of historical progress in a single year, about the distance from Claude 2.1 to Sonnet 4.5. The 95% confidence interval runs from 1.5× to 2.8×, and METR’s broader judgment is that capabilities on well-specified tasks are improving at around twice the March 2024 to October 2025 rate — though it would not be surprised if the true figure were closer to 1.3× or 3×.
This is not just more compute
The first objection to a number like this is the obvious one: maybe Anthropic simply bought more GPUs. METR says it checked, and it is confident the acceleration was not due to faster growth in training compute. Instead, it attributes perhaps 80% of the current acceleration to AI itself — with the caveat that the figure is uncertain, and that other factors played a large role in late 2025.
What does “AI doing the research” actually mean here? Not a self-improving loop running unsupervised in a datacenter. METR is careful on this point: current gains are primarily AI-assisted rather than fully autonomous, and AI is not yet capable of highly significant, fully autonomous contributions to the most important stages of model training. But the evaluators say they saw signs that more autonomous contributions could become more important in the near future. The loop is closing; it has not closed.
The assessment had unusual depth. From August 12 to October 29, METR staff worked on Anthropic devices with internal data on pretraining, reinforcement learning, training compute, benchmark scores for internal models — including three unreleased models trained since July — AI speedup analyses, and forecasts of a future model’s metrics, plus about 15 staff interviews. METR took no payment. Its most advanced internal model in the report, called Model 4, scored 178.6 on AECI and above 50% on all 15 benchmarks METR examined for it.
The number you can’t check
Here is the problem with the report, and METR is unusually frank about it: Anthropic redacted a majority of the evidence METR found most informative. The company held unilateral redaction rights over all non-public information, and used them — Anthropic described the redactions as aimed at removing confidential information that could accelerate other AI developers. The public version is a roughly 100-page report whose most important risk conclusions rest on evidence the public cannot see.
That makes the 1.9× figure an act of trust in an evaluator rather than a checkable measurement. METR’s own robustness checks span 1.1× to 2.9× depending on a single modeling choice. It received no sample access to non-public models, and a planned verification of compute allocation was canceled after Anthropic changed the scope. None of that makes the headline wrong — but it does mean the strongest claim in AI safety this year arrives with its supporting evidence blacked out.
Anthropic said it hadn’t crossed the line. METR disagrees — politely
The report also lands in the middle of a live policy dispute. Anthropic’s Responsible Scaling Policy, version 3.4, effective July 8, defines a “2× Acceleration Threshold”: progress roughly doubling, substantially attributable to automation of AI research. In its August 2026 Risk Report, Anthropic said acceleration was less than a factor of two. METR’s companion review of that report says the argument that the threshold was not crossed is overstated — that crossing was plausible by July 15, and that the public report understates the acceleration that was occurring. METR calculated about 1.97× from figures in Anthropic’s own private report.
Anthropic’s own system cards tell a similar story from a different angle: the Claude Opus 5.5 card reported a slope increase of about 1.53× and concluded the slope had not doubled; the Haiku 5.5 card put it at 1.7×. Most researchers at both METR and Anthropic lean toward the threshold not having been crossed — but “most lean” is not the same as “settled,” and the distance between 1.7× and 2× is now a rounding error away from a policy tripwire.
Why this number matters more than a benchmark
A 1.9× acceleration in the rate of progress is not the same as models being 1.9× smarter. It is a rate-of-change claim, and rate-of-change claims are what break plans. Safety evaluations, governance timelines, and deployment decisions are all calibrated to a world where progress arrives at a known speed. If the speed itself is doubling because the research workforce is increasingly made of the product, then every forecast built on the old slope is quietly out of date — including the forecasts inside the labs.
Three questions decide what happens next. First, does the acceleration hold, or was late 2025 a one-time step change from better tooling that will flatten? Second, do other labs show the same pattern when someone measures them — or is this an Anthropic-specific story about Claude’s strength at research tasks? Third, and most important: at what point does “AI-assisted” become “AI-autonomous” in the stages of training that matter, and will anyone outside the lab be able to see it happen when it does?
METR’s report does not answer those questions. What it does — and this is why it matters — is put the first independently measured number on the feedback loop the whole field has been arguing about in the abstract. The loop is real, it is roughly doubling the pace, and the evidence for how far it has gone is sitting behind a redaction bar. That combination — a measured acceleration and an unverifiable evidence base — is the story of AI governance in 2026 in miniature.
Sources: METR, “Independent Assessment of AI R&D Acceleration at Anthropic in October 2026” (November 5, 2026); METR’s companion review of the automated R&D section of Anthropic’s August 2026 Risk Report; Reuters, “Anthropic’s models improving nearly twice as fast with help from AI, study finds” (November 5, 2026); Anthropic system cards for Claude Opus 5.5 and Haiku 5.5. METR states Anthropic redacted a majority of the most informative evidence; figures cited are METR’s estimates, not independently verified measurements.